
Speech to Text
Real-Time Whisper Transcription
RUN
Background
This tool produces a real transcript of what is said — word content, not vocal tone — using Whisper, currently the most accurate open speech-recognition model available, run entirely in the browser via Transformers.js. No audio ever leaves the page: the model downloads once (cached by the browser afterwards) and all transcription happens on-device.
This is different from the toolkit's Live Speaker Transcript tool, which uses the browser's built-in Web Speech API for instant live captions and only calls Whisper for uploaded video. Web Speech API transcription quality varies a lot by browser and struggles with accents, background noise, and non-English speech. Whisper is slower and runs in short chunks rather than word-by-word, but is substantially more accurate and works the same way in every browser. Use this tool when transcript quality matters more than instant feedback or speaker attribution; use Live Speaker Transcript when you need to know which face was talking.
Process
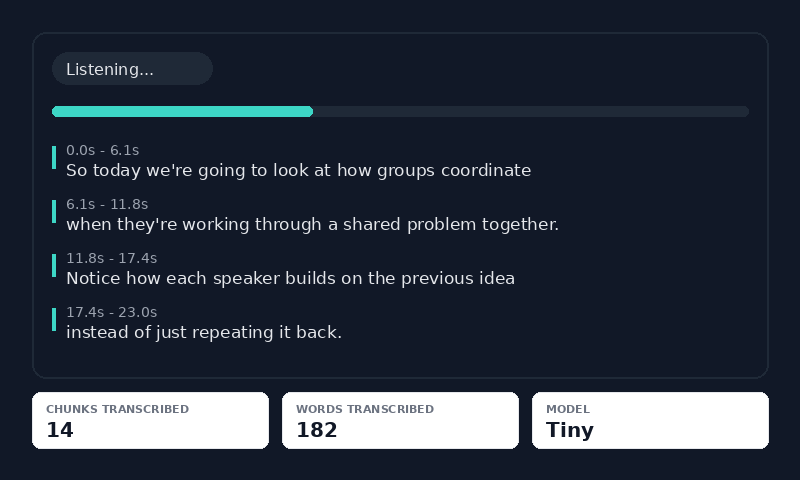
Audio from the live microphone (or an uploaded audio/video file) is captured continuously and transcribed in rolling chunks (4–10 seconds, configurable in the settings panel). Because Whisper is not a streaming model, each chunk is transcribed only once it finishes — so the live transcript lags the chunk length behind real speech, rather than appearing word-by-word like Live Speaker Transcript's Web Speech API captions. If a chunk is still being transcribed when the next one would start, audio keeps accumulating rather than being dropped, so no speech is lost — the chunk is just a little longer than usual. Each committed chunk is appended to the transcript panel and logged as one row for CSV export.
Uploaded audio/video is transcribed in full using Whisper's own 30-second windowing, which is more accurate than the live chunking above since it isn't constrained to keep pace with real time.
Results
The run page follows the toolkit's standard workflow: transcribe live from the microphone or transcribe an uploaded audio/video file, tag moments, view a session overview, and download the prediction CSV. Each CSV row is one transcribed chunk with its start/end time and text.
References
- Whisper: Robust Speech Recognition via Large-Scale Weak Supervision (Radford et al., 2022)
- Models: Xenova/whisper-tiny, Xenova/whisper-base
- Transformers.js: https://github.com/huggingface/transformers.js